Posted on

AI, Bubble or Boom?

Thoughts of the Fractional Chief

The Structural Economics, Regulatory Realities,
and Enterprise Lock-In Shaping the Frontier AI Market

Introduction:
The Multi-Trillion Dollar Paradox

The narrative dominating corporate boardrooms compares current private AI valuations against decades of historical technology IPOs.
The assumption is linear and seductive: exponential model performance will drive exponential market value (x+1), creating a multi-trillion-dollar software paradigm shift.

However, a fundamental divergence exists between speculative valuation and operating reality. Legacy tech giants like Microsoft, Google, Meta, and Apple went public or scaled on proven unit economics, generating hundreds of billions in compounding free cash flow. Frontier AI labs, by contrast, are executing the most capital-intensive buildout in corporate history—burning billions in compute and R&D before proving long-term, self-sustaining profitability.

To determine whether AI represents a lasting economic boom or a structural bubble, we must evaluate the underlying math: token unit economics, capital recovery timelines, vendor lock-in, and an accelerating global regulatory framework.

Section 1: The Math of the “AI Currency” – Inference vs. Training

In the AI economy, the token is the fundamental billable unit. It represents the quantifiable output of compute time, silicon wear, and energy. However, token pricing currently masks a deep economic divide within frontier labs:

  • High Gross Margins on Inference: Serving an output token to a client (inference) carries healthy gross margins – often 75% to 85% on standard enterprise API tiers. The variable cost (electricity and GPU runtime) is relatively low per query.

  • The R&D Treadmill: High inference margins are routinely devoured by upfront capital expenditure (CapEx) and pre-training costs. Building a next-generation base model requires billions of dollars in silicon clusters, data licensing, and power infrastructure before a single query is run. Because base models become commercially obsolete every 12 to 18 months, labs cannot amortize training costs over a multi-year software lifecycle.

The Cost-to-Income Recovery Gap

When evaluating total corporate expenses (including multi-billion-dollar compute commitments and R&D) against top-line revenues, frontier labs operate at severe loss-to-income multiples:

  • OpenAI: Operating with an expense base roughly 2.6x higher than recognized income (e.g., ~$34B in total expenses against ~$13B in revenue in 2025), its baseline operations require a 2.6x top-line expansion merely to break even. To recover historical losses, service debt, and achieve standard technology profit margins, overall monetization must scale 5x to 7x.

  • Anthropic: Facing an initial burn-to-income ratio reaching 7x during peak model training phases, its long-term capital recovery model requires a 10x to 12x return factor relative to its early monetization baseline.

Section 2: Why Token Prices Can’t Just “Scale Up 10x”

If an enterprise lab faces a 5x to 12x gap between current income and full capital recovery, why not simply raise unit token prices?In software economics, attempting to close a corporate expense gap via a 1000% raw unit price hike triggers immediate market failure:
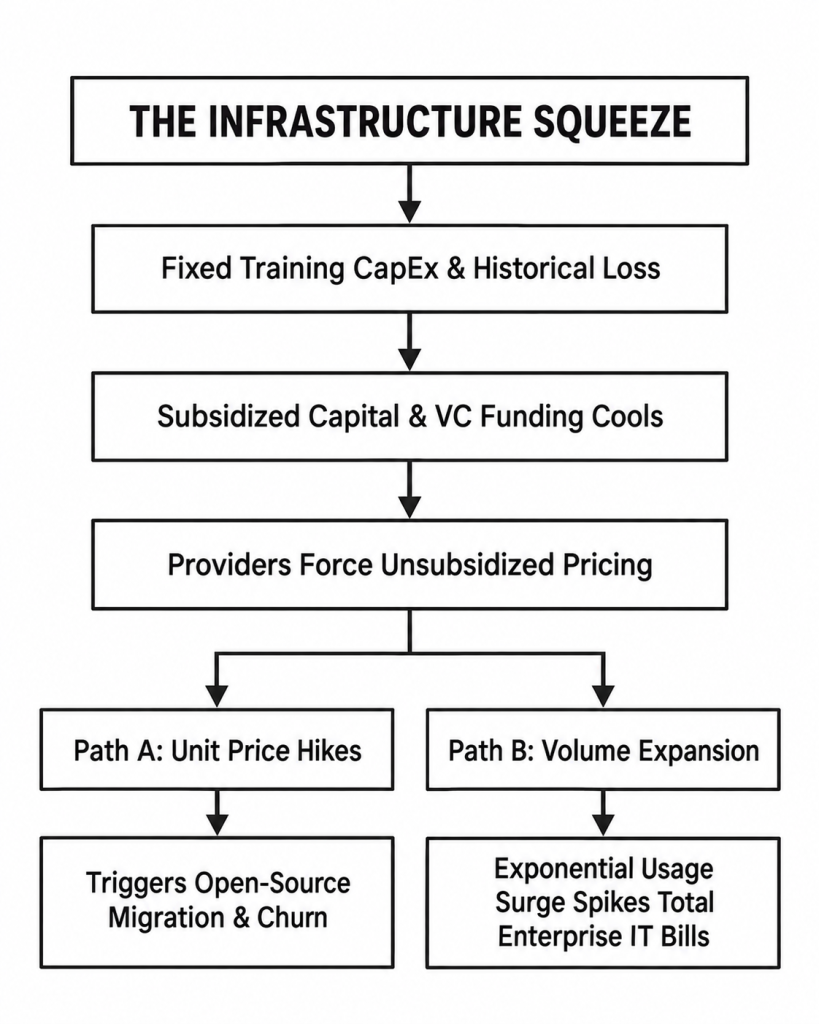
  1. The Open-Source Ceiling: Open-source architectures (e.g., Meta’s Llama series, Qwen, DeepSeek) provide a natural price ceiling. If proprietary labs increase raw token fees by multiples, enterprise clients will migrate workloads to self-hosted or local cloud clusters.

  2. The Real Expense Multiplier – Volume: The financial shock to enterprise clients will not stem from a 10x increase in the price per token, but from a 10x to 15x surge in cumulative compute consumption. As companies move from basic search prompts to autonomous, background-running “agentic workflows” –
    where models loop continuously to execute multi-step logic – token consumption scales exponentially.

An enterprise spending $20,000/month on simple API calls today can easily see that bill expand to $250,000/month as autonomous agents deploy at scale.

Section 3: The Single-Supplier Lock-In Trap

Many enterprise executives treat LLM integration like a standard SaaS subscription, assuming they can switch providers if pricing or terms change. In practice, deep AI integration creates unprecedented operational lock-in:

  • Architectural Coupling: Prompts, system instructions, guardrails, context windows, and multi-agent routing logic are tuned specifically to individual model behaviors. Switching from one provider to another often breaks subtle reasoning chains, requiring months of re-engineering.

  • The Margin Squeeze: As subsidized VC capital cools and providers pass unsubsidized compute costs down to enterprise buyers, locked-in clients face a difficult choice: absorb higher operational costs, pass cost increases onto end customers (risking demand drop-off), or undertake costly model migrations.

When enterprise buyers realize that AI integration squeezes their own operating margins rather than expanding them, user adoption curves risk stalling.

Section 4: The Regulatory TAM Squeeze (EU AI Act & Geopolitical Risk)

The assumption that frontier labs will enjoy friction-free global TAM (Total Addressable Market) expansion is directly challenged by tightening regulation and geopolitical policy.
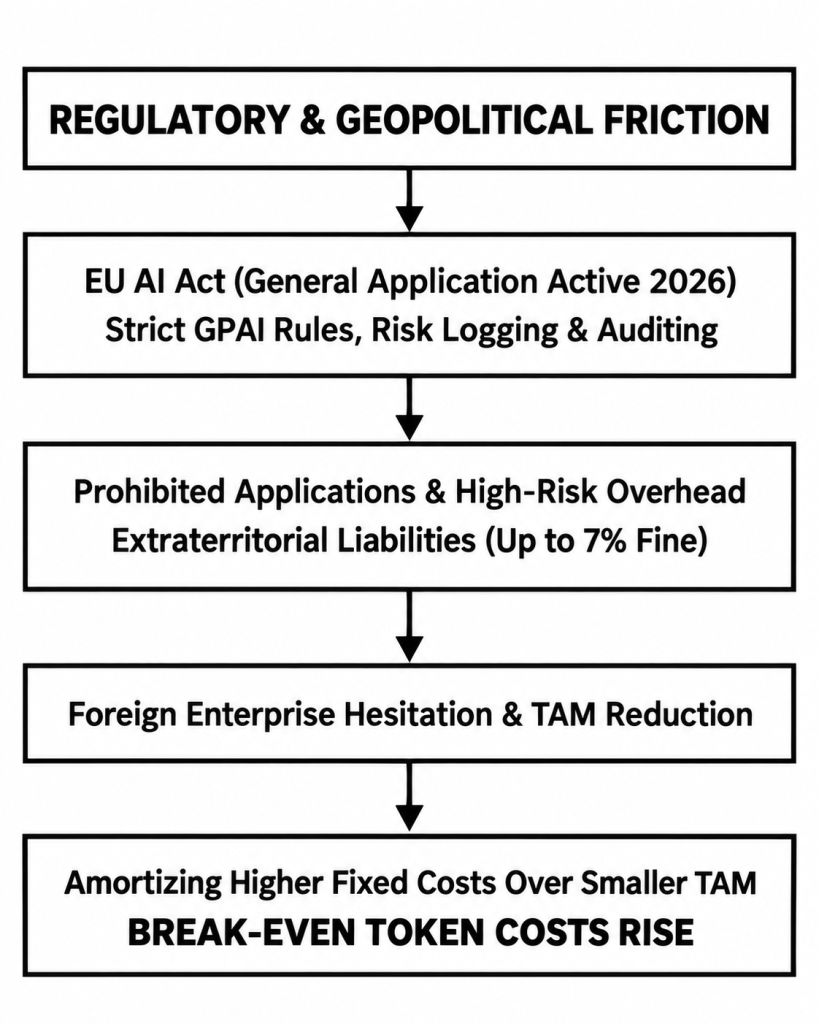
1. Regulatory Compliance as a Fixed Overhead

The full application of the EU AI Act enforces rigorous compliance mandates across Europe:

  • GPAI & Transparency Rules: Providers of General Purpose AI models face strict documentation, copyright compliance, and systemic risk management requirements.

  • High-Risk Liabilities: Deploying AI in high-risk categories (employment, credit scoring, critical infrastructure) requires extensive risk audits and logging. Downstream deployers who customize models risk inheriting full provider liability, carrying potential fines up to €35 million or 7% of global annual turnover.

2. Geopolitical Export Controls & Single-Vendor Risk

Enforcement actions – such as global model freezes or export control restrictions mandated by U.S. regulatory directives have highlighted single-vendor risk for international clients.

When global enterprise buyers realize access to proprietary models can be restricted or modified overnight due to foreign trade policy, reliance on single-country proprietary providers becomes a strategic liability.

3. The Mathematical Impact on Break-Even

Regulation creates a double-whammy: it increases compliance and legal overhead (expanding the numerator of required costs) while simultaneously restricting or delaying product categories and foreign enterprise adoption (shrinking the denominator of Total Addressable Market volume).

\text{Required Price per Token} = \frac{\text{Fixed Capital Costs} + \text{R\&D Losses} + \text{Regulatory Compliance Overhead}}{\text{Addressable Market Volume } (\text{Shrunk by Compliance Friction \& Geopolitical Risks})}

If the addressable market contracts due to compliance hurdles and single-vendor risk,
the unit cost required to recover capital investments increases.

Conclusion: The Strategic Correction Ahead

Is AI a bubble or a boom?

The underlying technology represents a transformative industrial shift,but the current financial model backing multi-trillion-dollar valuations faces a structural correction.

The market has priced in exponential growth without accounting for the realities of capital recovery, unsubsidized compute costs, deep enterprise lock-in, and global regulatory friction.

When private subsidies cool and enterprise buyers are forced to account for the true, unsubsidized cost of compute against their own operating margins, the market will shift away from speculative valuation toward fundamental economic discipline.

The companies that survive the coming correction will be those built on sustainable unit economics, architectural flexibility, and transparent ROI.
Posted on

Unicorn job specs…

Thoughts of the Fractional Chief

The rocky edition is at the bottom of the post!

Unicorn job specs are getting more and more common, where unreasonable demands such as:
You can’t be more than 20, you need an MBA or a computer science degree with 15 years experience in a professional setting, and you also need to match our corporate tech stack perfectly, as if you were a previous employee, which you, by the way, can’t be, Never mind understanding and matching our corporate culture (that you have never seen or experienced)… 

Then hearing leaders and recruiters complain about “there’s no candidates” after AI matching and removing any candidate that doesn’t fit these job specs, which almost guarantees 100% removal of any viable person. 

I wonder why that is. 

In practical reality, there is a few things that really matters.
If you see someone matching the basics, has the basic fundamental knowledge and seems to be the possible match, have a quick 10-minute call with them and figure out the rest, because that quick call will tell you who they are, their attitude and a bit of their pesonality.

Use the pre-scanning to sort out the chaff from the wheats, as in those applied, but do not have the industry experience or basic capabilities versus those who actually has it, because not everything is listed in the CV, but only told through their voice. 

When hiring, you are NOT looking for a replacement of someone you never had, impossible combinations or someone to replace your previous employee.
What you are REALLY looking for, is a person that can solve problems, not just in a a specific tech stack, but genericly, one that can bring new fresh ideas, expand your business, their adapability, their general ability to solve problems and come up with new ideas, and most importantly, the right attitude, as this is the one thing that bridges them all and can work wonders, where the wrong one… 

Anything else, is unicorn dreams.

There is no real shortage of people, just an extreme abundance of bad recruitment and unrealistic demands for combinations in job specs, that does not exist in real life.

The ones who looks beyond, is the ones who lands the good people. 

Lyrics: 

Unicorn Job Spec

Verse 1
Recruiter’s got a clipboard,
And a sparkle in their eye,
“Must be twenty, senior-level,
With a decade on the sly.”
They want startup grit and corporate polish,
MBA and code,
Five frameworks, three dead languages,
And “good vibes” on the road.

Pre-Chorus
They say, “We just need culture fit,”
Which sounds suspiciously like,
“Can you read our minds by Tuesday
And pretend you own a bike?”

Chorus
Stop chasing unicorns, darling,
They’re not hiding in the stack,
You want fifteen years’ experience
On a baby’s lower back.
Perfect match, exact same tooling,
Never needs to be shown,
But the real ones learn, adapt, solve fast,
And don’t cry when left alone.

Verse 2
The CV says “GoLang, Docker,”
But the job says “also React,”
Then Kubernetes, sales support,
And “light finance” as a fact.
“Must thrive under pressure,”
“Must be humble, must be keen,”
Translation: “We are chaos
In a Patagonia fleece.”

Pre-Chorus
You can scan a hundred résumés,
And still not spot the spark,
But a ten-minute intro call
Can light the bloody dark.

Chorus
Stop chasing unicorns, darling,
They’re not grazing by your desk,
You want plug-and-play perfection
With a halo and no stress.
Perfect match, same stack, same habits,
Same weird office tea,
But give me grit, a brain, some humour,
And the nerve to disagree.

Bridge
There’s no talent shortage,
Just a fantasy buffet,
Where every job spec’s drunk at midnight
Writing filth in HR grey.
“Rockstar ninja wizard wanted,”
With compliance and a smile,
Paying junior money proudly,
For a full-stack demigod profile.

Final Chorus
Stop chasing unicorns, darling,
Put the fairy dust away,
Skills can grow and stacks can change,
But attitude will stay.
You can’t hire perfect from a keyword,
You can’t filter out the soul,
So pick the ones who learn, solve, laugh,
And drag the mess towards the goal.

Outro
So here’s to the awkward intro call,
The CV that undersells,
The clever sod with no buzzwords,
Who can fix your burning hells.
The unicorn is fiction,
The job spec needs a drink,
Hire humans, not hallucinations,
And maybe learn to think.


Posted on

AI – Hype or actually useful?

Thoughts of the Fractional ChiefTL;DR

Primarily from a tech view, there is a lot of talk today about AI,
and a lot of that talk is exagerrated hype, overconfidence and
sometimes outright false claims, especially by some companies
that claim AI can generate 100% error-free code and outperforms
regular devs by 1000x. 

Let’s be a bit more realistic about the expectations and possibilities.

What is an LLM? 

It’s in the name – LLM stands for Large Language Model.

An LLM is software trained on large amounts of human language and related content, that at its core, predicts the likely next token(s) (words or pieces of words) given the prompt and the context.
In most real deployments it is probabilistic, meaning that if you allow sampling, two identical questions can produce different answers, and if you force deterministic decoding, you can get consistent outputs, but most likely, an incorrect response.

LLMs learn statistical patterns from what they were trained on: questions and answers from the internet, books, documentation, scientific writing, and code.
They can produce novel combinations of ideas by generalizing across those patterns, and all while this is very useful, it also means they can generate convincing text that is wrong.

AI models also use something called quantization, and while this is a simplification and not the only cause of mistakes, it can be a contributing factor.

Quantization reduces numeric precision inside the model (for example in the weights and sometimes activations) to make the model smaller and faster to run.

Conceptually it is like rounding: 1.0001 and 1.0002 may become 1.0 after rounding.
That kind of approximation can increase error rates, especially on harder reasoning tasks or long chains of inference, because small inaccuracies can (and will) compound as the reasoning progresses over time, and this extends into other sources similiar in context to “quantization”. See list at the end of the article. 

That said, hallucinations are not caused only by quantization – they can occur even without it, because the model is optimized to produce plausible text, not guaranteed truth, as all LLMs are effectively – statistical models.

Please do not get me wrong – I’m all for the use of AI, but it has to be an informed and responsible use, without the notion that it is always right and error-free, that it can be let to do anything without proper vetting by humans and so on – which are just plain dangerous and seemingly all too common misconceptions out in the wild.

Knowing how to, and using it responsibly can bring tremendous benefits to pretty much any organization, remembering the keywords: “How to” and “responsibly”. 

Bottom line:
There is no LLM today whose output you should treat as guaranteed correct – you still need to apply common sense, knowledge, and verification to the response.

So, security and autonomous agents?

Security and autonomous agents should not be treated lightly.
If you combine high privilege access with an agent that can produce “plausible” but wrong decisions, you are taking on a very real and high risk.

There are already examples of organizations learning this the hard way.
Reporting in February 2026 described AWS incidents where an internal AI coding agent (Kiro) was involved in a 13 hour outage in December 2025 after deleting and recreating an environment, with Amazon attributing the root cause to misconfigured permissions and process failures rather than “the AI” alone.
Ref: Amazon’s AI deleted production. Then Amazon blamed the humans.

The lesson is simple: do not let an AI control production or security critical systems without strict constraints and prior human approvals combined with auditing.
If you use AI for anything that can affect production, vet it first.
If all it does is produce text, the risk is much lower, but if it can take (unmonitored) actions, the bar must be set much higher.

So then, what is it good for?  

Now you may think, so what can I use it for then? 

Now that you understand what it is, the practical uses become obvious – treat it like a smart collaborator you can use to offload lower level tasks:

  • writing a function or two
  • scaffolding
  • generating test modules
  • drafting documentation
  • summarizing tickets, logs, or discussions
  • try concepts and solutions
  • hunt down stubborn and hard to find bugs, given good input.

You still review and own the output, but you do not have to type everything.

It is a power tool. You can talk to it, reason with it, and use it to explore ideas.
You can use it to analyze how text is likely to be perceived by others.
You can use it to help hunt bugs and narrow down hypotheses if you provide solid context – It can save hours, or even days..

Fast research of complex questions can also work well: it can combine and condense large sets of information into something usable.
You just have to verify anything important, before you use it. 

The key to success is: bring a good specification. 
Be very precise about your functional requirements and the data models, with examples of the data and formats, and you will have a higher rate of success.
Also be equally precise about the do’s and don’ts, as this will set the borders for the AI to work with during the creation of what you want.   

In short, assume the worst and create a clear specification of what you do/don’t want with the limits and everything, as if the actor is an inexperienced human doing it for the first time. 

Ok, so, what are the practical limitations? 

… you ask. 

Because models can hallucinate and make mistakes, do not blindly copy-paste and run generated code, or other output, as if it is perfect.
Use it safely:

  • if the output is trivial, you may be able to validate it at a glance
  • otherwise, review it, test it, and treat it like a draft from a junior engineer or colleague. 

Also, the old adage still goes – garbage in – garbage out.
Vague prompts produce vague results, and this is true for humans too.
“I am hungry, bring me something to eat” can easily result in your least liked dish.
If you want useful output, give clear requirements and constraints.

Do not assume it will “just know” what you meant.

Architecture, mostly

For higher level architecture, be cautious.
Context windows are limited, and long projects exceed what the model can consistently hold in working memory.
That often leads to linear solutions, duplicated logic, and “works in isolation” code that becomes spaghetti when assembled into an application.

You can partially mitigate this, but it takes discipline:

  • provide tight specifications
  • use simple explicit constraints like “must”, “must not”, and “shall”, and keep the samples simple and short. 
  • force modular boundaries and interfaces
  • provide examples of required data models where possible. 
  • require tests and acceptance criteria

Agentic AI

Keep the rules simple: 

  • Never let agents freely control everything and make autonomous decisions on your behalf.
  • Be explicit about
    • what they can do,
    • what they cannot do,
    • and what requires a human approval step.

If in doubt, hard-limit the last 2 steps, by not giving them the interface to act. 
(access to credentials, chatbot groups for interchange (risk of cred/data leakage), or direct execution control.)

Additional reasons for hallucinations and limitations of AI models

Just like expressed before with the decimal quantization example, these are also limitations in terms of precision or similar limitations that add to the fact that models hallucinate. 
The limitations are in principle similar to the quantization, by limiting of precision in the sources or even removal of sources, conflicting data, too much simplification, short attention spans (forgetfulness) and so on as in the examples below: 

  • Objective mismatch: plausible vs true
    LLMs are trained to predict the next token that fits the context, not to prove statements are true.
    When the model is uncertain, it will often still produce something that sounds coherent.

  • Missing or ambiguous context
    If the prompt does not include key facts, constraints, or definitions, the model fills gaps with the most likely completion.
    That is where confident wrong details show up.

  • No built-in source of truth
    Unless the system is explicitly connected to retrieval (docs, database, search) and forced to use it, the model is relying on its internal patterns, which are not a reliable fact store.

  • Training data gaps and conflicts
    Training data contains errors, outdated info, and contradictions.
    The model can blend incompatible sources or pick a common but wrong pattern.

  • Overgeneralization from patterns
    LLMs are good at analogies. Sometimes they apply the right shaped pattern to the wrong situation and generate an answer that looks structurally correct but is factually incorrect.

  • Decoding settings and randomness
    Sampling settings (temperature, top-p, etc.) increase diversity but also increase risk of inventing details.
    Deterministic decoding reduces variance but can still be wrong, just consistently wrong.

  • Long context and attention limits
    With long prompts or multi-step tasks, important details can be missed, diluted, or overshadowed by more recent or more frequent cues. Errors then cascade.

  • Weak grounding in math and multi-step verification
    They can produce fluent reasoning text without actually checking intermediate steps.
    If a system does not force external checks (calculators, unit tests, compilers), they will sometimes “talk through” mistakes.

  • Quantization and smaller models (contributing factor)
    Lower precision and smaller models can degrade accuracy and increase error rates, but they are not the root cause.
    Full precision large models hallucinate too.