Posted on

DASH

Thoughts of the Fractional Chief

Ok… I’m guilty. I made it.

Yes, it is another acronym. But this one is deliberately simple.
DASH is the way we approach practical, time-boxed work inside a business:
diagnose the issue, align on the fix, solve it, and hand it over working.

That is why it matters for PE-backed businesses.

Most teams do not need another workshop or strategy deck, but they need someone close enough to the business to find a real problem,
fix it, and leave behind something measurable.

What you need, is a specific and confined swat team equivalence for your problem, small or large. 

DASH is a simple, typically below 30-day delivery model for portfolio companies that need practical work done quickly.

It stands for:

  • Diagnose – understand the real issue(s)
  • Align – agree on a practical solution
  • Solve – solve the problem
  • Handover – ship it and leave it working.

No need for big programmes, workshop theatre, slide decks, lost time,
never-ending meetings, costly pre-studies, or fat reports.
Just diagnose the problem, align so everyone knows what is expected and what the
outcome should look like, solve it, then hand over a sustainable working solution.

DASH is its own execution mode.

It is not a replacement for agile, waterfall, roadmaps, or normal planned delivery.
Those are still the right places for larger bodies of work, grouped initiatives,
platform changes, and long-running programmes.

DASH is for the single issue that needs direct intervention.

  • One problem.
  • One focused team.
  • One measurable outcome.
  • One handover.

That is the difference.

Key notes on execution:

  • DASH is meant to be lean and rapid, providing the shortest practical path from start to finish.  
    Do not bring more people into each stage than needed – on the contrary, keep people out of their way, unless they specifically need to be there.

  • DASH follows a standard delivery flow:
    Requirements → Specification/scoping → Intent → Implementation → QA → Deployment,

    Requirements and specification/scoping sit inside Diagnose.
    Intent maps to Align – agree with stakeholders on what and how, lock out scope creep.
    Implementation and QA sit inside Solve.
    Deployment becomes Handover.

  • DASH does not necessarily follow agile methods.
    It can, where that helps, but the point is
    to solve specific issues quickly and efficiently, with focused effort from the people involved.

  • It is not a sprint, as there is no set time for fix – but – ASAP. 

  • Clear authority to act within preset limits. 
    As a DASH team, if you do not have the authority to act, but have to wait for every step to be authorized, you will be held up.

  • Handover Includes the “mop-up”, delivering the operating instructions, not just fixing the problem, but enabling the people to operate it properly and safely.

  • People who are not specifically required, shall not attend, but may/should be kept informed. 
    • Keep meetings down, maximise execution. 
    • Keep meetings only with the ones that needs to be there.
    • Keep stakeholders informed, async, not by meetings.

Think of it as a task force: linear, practical, and moving from start to finish.  


… and it’s not just for tech. It works in any setting:

1. In Sales & Marketing

  • Diagnose: Customer acquisition cost (CAC) is spiking because leads are rotting in the pipeline for 5 days before anyone calls them.
  • Align: Agree with the VP of Sales and CMO that any lead not called within 15 minutes gets auto-routed to a dedicated “speed-to-lead” rep.
  • Solve: Build the automated routing rules in the CRM and write the instant-response scripts.
  • Handover: Go live, train the reps, and show the PE firm a drop in lead response time by Day 30.

2. In Finance / RevOps

  • Diagnose: The portfolio company is leaking cash because they have dozens of orphaned, duplicate software subscriptions across 5 departments.
  • Align: Agree with the CFO on a strict “one tool per function” policy and an immediate budget freeze on unapproved SaaS.
  • Solve: Audit the bank statements, cancel the redundant licenses, and renegotiate contracts with the core vendors.
  • Handover: Hand the CFO a clean, consolidated tech stack and a ledger showing $15,000 in monthly recurring savings.

3. In Supply Chain & Operations

  • Diagnose: E-commerce order fulfillment is backed up because the warehouse layout forces packing staff to walk twice as far as they need to.
  • Align: Agree with the Warehouse Manager on a new “high-velocity zone” layout for the top 20% best-selling items.
  • Solve: Spend a weekend physically moving the inventory, updating the bin locations in the system, and taping out the new floor paths.
  • Handover: Ship the new workflow live and measure the 25% increase in daily order throughput.

4. In HR & Talent

  • Diagnose: The company is losing top engineering candidates because the interview process takes 6 weeks and 7 rounds of interviews.
  • Align: Agree with the hiring managers to compress the process into 3 rounds over a maximum of 5 business days.
  • Solve: Rewrite the interview rubrics, block out standard evaluation times on managers’ calendars, and automate the scheduling links.
  • Handover: Roll it out for the next active job opening and watch the candidate drop-out rate plunge.

5. In Technology / Engineering

  • Diagnose: The application’s checkout page has a massive bounce rate because the page takes 4.5 seconds to load, causing users to abandon their carts.
  • Align: Agree with the Product Manager and Lead Architect that optimizing the heavy database queries and compressing the product images is the fastest way to get load times under 1.5 seconds.
  • Solve: Rewrite the inefficient SQL queries, implement a caching layer, and set up automated image compression in the deployment pipeline.
  • Handover: Deploy the code to production, monitor the server logs to prove the 3-second speed increase, and hand over the dashboard to the infrastructure team.
 

Posted on

Unicorn job specs…

Thoughts of the Fractional Chief

The rocky edition is at the bottom of the post!

Unicorn job specs are getting more and more common, where unreasonable demands such as:
You can’t be more than 20, you need an MBA or a computer science degree with 15 years experience in a professional setting, and you also need to match our corporate tech stack perfectly, as if you were a previous employee, which you, by the way, can’t be, Never mind understanding and matching our corporate culture (that you have never seen or experienced)… 

Then hearing leaders and recruiters complain about “there’s no candidates” after AI matching and removing any candidate that doesn’t fit these job specs, which almost guarantees 100% removal of any viable person. 

I wonder why that is. 

In practical reality, there is a few things that really matters.
If you see someone matching the basics, has the basic fundamental knowledge and seems to be the possible match, have a quick 10-minute call with them and figure out the rest, because that quick call will tell you who they are, their attitude and a bit of their pesonality.

Use the pre-scanning to sort out the chaff from the wheats, as in those applied, but do not have the industry experience or basic capabilities versus those who actually has it, because not everything is listed in the CV, but only told through their voice. 

When hiring, you are NOT looking for a replacement of someone you never had, impossible combinations or someone to replace your previous employee.
What you are REALLY looking for, is a person that can solve problems, not just in a a specific tech stack, but genericly, one that can bring new fresh ideas, expand your business, their adapability, their general ability to solve problems and come up with new ideas, and most importantly, the right attitude, as this is the one thing that bridges them all and can work wonders, where the wrong one… 

Anything else, is unicorn dreams.

There is no real shortage of people, just an extreme abundance of bad recruitment and unrealistic demands for combinations in job specs, that does not exist in real life.

The ones who looks beyond, is the ones who lands the good people. 

Lyrics: 

Unicorn Job Spec

Verse 1
Recruiter’s got a clipboard,
And a sparkle in their eye,
“Must be twenty, senior-level,
With a decade on the sly.”
They want startup grit and corporate polish,
MBA and code,
Five frameworks, three dead languages,
And “good vibes” on the road.

Pre-Chorus
They say, “We just need culture fit,”
Which sounds suspiciously like,
“Can you read our minds by Tuesday
And pretend you own a bike?”

Chorus
Stop chasing unicorns, darling,
They’re not hiding in the stack,
You want fifteen years’ experience
On a baby’s lower back.
Perfect match, exact same tooling,
Never needs to be shown,
But the real ones learn, adapt, solve fast,
And don’t cry when left alone.

Verse 2
The CV says “GoLang, Docker,”
But the job says “also React,”
Then Kubernetes, sales support,
And “light finance” as a fact.
“Must thrive under pressure,”
“Must be humble, must be keen,”
Translation: “We are chaos
In a Patagonia fleece.”

Pre-Chorus
You can scan a hundred résumés,
And still not spot the spark,
But a ten-minute intro call
Can light the bloody dark.

Chorus
Stop chasing unicorns, darling,
They’re not grazing by your desk,
You want plug-and-play perfection
With a halo and no stress.
Perfect match, same stack, same habits,
Same weird office tea,
But give me grit, a brain, some humour,
And the nerve to disagree.

Bridge
There’s no talent shortage,
Just a fantasy buffet,
Where every job spec’s drunk at midnight
Writing filth in HR grey.
“Rockstar ninja wizard wanted,”
With compliance and a smile,
Paying junior money proudly,
For a full-stack demigod profile.

Final Chorus
Stop chasing unicorns, darling,
Put the fairy dust away,
Skills can grow and stacks can change,
But attitude will stay.
You can’t hire perfect from a keyword,
You can’t filter out the soul,
So pick the ones who learn, solve, laugh,
And drag the mess towards the goal.

Outro
So here’s to the awkward intro call,
The CV that undersells,
The clever sod with no buzzwords,
Who can fix your burning hells.
The unicorn is fiction,
The job spec needs a drink,
Hire humans, not hallucinations,
And maybe learn to think.


Posted on

AI – Hype or actually useful?

Thoughts of the Fractional ChiefTL;DR

Primarily from a tech view, there is a lot of talk today about AI,
and a lot of that talk is exagerrated hype, overconfidence and
sometimes outright false claims, especially by some companies
that claim AI can generate 100% error-free code and outperforms
regular devs by 1000x. 

Let’s be a bit more realistic about the expectations and possibilities.

What is an LLM? 

It’s in the name – LLM stands for Large Language Model.

An LLM is software trained on large amounts of human language and related content, that at its core, predicts the likely next token(s) (words or pieces of words) given the prompt and the context.
In most real deployments it is probabilistic, meaning that if you allow sampling, two identical questions can produce different answers, and if you force deterministic decoding, you can get consistent outputs, but most likely, an incorrect response.

LLMs learn statistical patterns from what they were trained on: questions and answers from the internet, books, documentation, scientific writing, and code.
They can produce novel combinations of ideas by generalizing across those patterns, and all while this is very useful, it also means they can generate convincing text that is wrong.

AI models also use something called quantization, and while this is a simplification and not the only cause of mistakes, it can be a contributing factor.

Quantization reduces numeric precision inside the model (for example in the weights and sometimes activations) to make the model smaller and faster to run.

Conceptually it is like rounding: 1.0001 and 1.0002 may become 1.0 after rounding.
That kind of approximation can increase error rates, especially on harder reasoning tasks or long chains of inference, because small inaccuracies can (and will) compound as the reasoning progresses over time, and this extends into other sources similiar in context to “quantization”. See list at the end of the article. 

That said, hallucinations are not caused only by quantization – they can occur even without it, because the model is optimized to produce plausible text, not guaranteed truth, as all LLMs are effectively – statistical models.

Please do not get me wrong – I’m all for the use of AI, but it has to be an informed and responsible use, without the notion that it is always right and error-free, that it can be let to do anything without proper vetting by humans and so on – which are just plain dangerous and seemingly all too common misconceptions out in the wild.

Knowing how to, and using it responsibly can bring tremendous benefits to pretty much any organization, remembering the keywords: “How to” and “responsibly”. 

Bottom line:
There is no LLM today whose output you should treat as guaranteed correct – you still need to apply common sense, knowledge, and verification to the response.

So, security and autonomous agents?

Security and autonomous agents should not be treated lightly.
If you combine high privilege access with an agent that can produce “plausible” but wrong decisions, you are taking on a very real and high risk.

There are already examples of organizations learning this the hard way.
Reporting in February 2026 described AWS incidents where an internal AI coding agent (Kiro) was involved in a 13 hour outage in December 2025 after deleting and recreating an environment, with Amazon attributing the root cause to misconfigured permissions and process failures rather than “the AI” alone.
Ref: Amazon’s AI deleted production. Then Amazon blamed the humans.

The lesson is simple: do not let an AI control production or security critical systems without strict constraints and prior human approvals combined with auditing.
If you use AI for anything that can affect production, vet it first.
If all it does is produce text, the risk is much lower, but if it can take (unmonitored) actions, the bar must be set much higher.

So then, what is it good for?  

Now you may think, so what can I use it for then? 

Now that you understand what it is, the practical uses become obvious – treat it like a smart collaborator you can use to offload lower level tasks:

  • writing a function or two
  • scaffolding
  • generating test modules
  • drafting documentation
  • summarizing tickets, logs, or discussions
  • try concepts and solutions
  • hunt down stubborn and hard to find bugs, given good input.

You still review and own the output, but you do not have to type everything.

It is a power tool. You can talk to it, reason with it, and use it to explore ideas.
You can use it to analyze how text is likely to be perceived by others.
You can use it to help hunt bugs and narrow down hypotheses if you provide solid context – It can save hours, or even days..

Fast research of complex questions can also work well: it can combine and condense large sets of information into something usable.
You just have to verify anything important, before you use it. 

The key to success is: bring a good specification. 
Be very precise about your functional requirements and the data models, with examples of the data and formats, and you will have a higher rate of success.
Also be equally precise about the do’s and don’ts, as this will set the borders for the AI to work with during the creation of what you want.   

In short, assume the worst and create a clear specification of what you do/don’t want with the limits and everything, as if the actor is an inexperienced human doing it for the first time. 

Ok, so, what are the practical limitations? 

… you ask. 

Because models can hallucinate and make mistakes, do not blindly copy-paste and run generated code, or other output, as if it is perfect.
Use it safely:

  • if the output is trivial, you may be able to validate it at a glance
  • otherwise, review it, test it, and treat it like a draft from a junior engineer or colleague. 

Also, the old adage still goes – garbage in – garbage out.
Vague prompts produce vague results, and this is true for humans too.
“I am hungry, bring me something to eat” can easily result in your least liked dish.
If you want useful output, give clear requirements and constraints.

Do not assume it will “just know” what you meant.

Architecture, mostly

For higher level architecture, be cautious.
Context windows are limited, and long projects exceed what the model can consistently hold in working memory.
That often leads to linear solutions, duplicated logic, and “works in isolation” code that becomes spaghetti when assembled into an application.

You can partially mitigate this, but it takes discipline:

  • provide tight specifications
  • use simple explicit constraints like “must”, “must not”, and “shall”, and keep the samples simple and short. 
  • force modular boundaries and interfaces
  • provide examples of required data models where possible. 
  • require tests and acceptance criteria

Agentic AI

Keep the rules simple: 

  • Never let agents freely control everything and make autonomous decisions on your behalf.
  • Be explicit about
    • what they can do,
    • what they cannot do,
    • and what requires a human approval step.

If in doubt, hard-limit the last 2 steps, by not giving them the interface to act. 
(access to credentials, chatbot groups for interchange (risk of cred/data leakage), or direct execution control.)

Additional reasons for hallucinations and limitations of AI models

Just like expressed before with the decimal quantization example, these are also limitations in terms of precision or similar limitations that add to the fact that models hallucinate. 
The limitations are in principle similar to the quantization, by limiting of precision in the sources or even removal of sources, conflicting data, too much simplification, short attention spans (forgetfulness) and so on as in the examples below: 

  • Objective mismatch: plausible vs true
    LLMs are trained to predict the next token that fits the context, not to prove statements are true.
    When the model is uncertain, it will often still produce something that sounds coherent.

  • Missing or ambiguous context
    If the prompt does not include key facts, constraints, or definitions, the model fills gaps with the most likely completion.
    That is where confident wrong details show up.

  • No built-in source of truth
    Unless the system is explicitly connected to retrieval (docs, database, search) and forced to use it, the model is relying on its internal patterns, which are not a reliable fact store.

  • Training data gaps and conflicts
    Training data contains errors, outdated info, and contradictions.
    The model can blend incompatible sources or pick a common but wrong pattern.

  • Overgeneralization from patterns
    LLMs are good at analogies. Sometimes they apply the right shaped pattern to the wrong situation and generate an answer that looks structurally correct but is factually incorrect.

  • Decoding settings and randomness
    Sampling settings (temperature, top-p, etc.) increase diversity but also increase risk of inventing details.
    Deterministic decoding reduces variance but can still be wrong, just consistently wrong.

  • Long context and attention limits
    With long prompts or multi-step tasks, important details can be missed, diluted, or overshadowed by more recent or more frequent cues. Errors then cascade.

  • Weak grounding in math and multi-step verification
    They can produce fluent reasoning text without actually checking intermediate steps.
    If a system does not force external checks (calculators, unit tests, compilers), they will sometimes “talk through” mistakes.

  • Quantization and smaller models (contributing factor)
    Lower precision and smaller models can degrade accuracy and increase error rates, but they are not the root cause.
    Full precision large models hallucinate too.


Posted on

Interim cover?

Thoughts of the Fractional ChiefIs it really the right solution for you?

Imagine this:
Your CTO (or another C-level leader) leaves, and overnight you’re in a management vacuum.

The teams start to struggle, because there is no overall technical direction in place, and you personally do not have the capacity or ability to fill the gap, especially not covering the tech. 

The team still has work to deliver. Someone still has to make decisions. Vendors still need answers. Security and operational issues don’t pause. The board still expects updates. And yet the person who used to hold all of that context has walked out the door.

So you do what most companies do: you start looking for an interim.

But what if the “interim” model isn’t actually the best fit?

The gap isn’t always full-time

In a lot of companies, the real problem isn’t that you need a permanent replacement immediately.
The real problem is that you need experienced decision-making and leadership continuity while you stabilise things.

That can mean:

  • keeping delivery moving without a new exec in place
  • making sure priorities don’t drift
  • reducing operational risk
  • helping the team stay focused and calm
  • creating a plan for the next 30–90 days
  • supporting a hiring process properly, instead of rushing it

And in many cases, you don’t need that support 40–60 hours a week.
You need it consistently, but not constantly.

A fractional executive fills the vacuum differently

A fractional portfolio executive is a senior leader who steps in on a part-time basis and takes ownership of the “executive-shaped” work that still needs doing.

They’re not a consultant who writes a report and disappears. They’re also not staff augmentation.
They’re there to:

  • lead decisions and create clarity
  • unblock execution
  • work with the team in the real world (not in theory)
  • support stakeholders, investors, and the board
  • stabilise operations while you figure out the long-term plan

The key difference is that it’s structured as ongoing leadership support, with a cadence, not a full-time role by default.

When fractional makes sense

Fractional leadership is often the right move when:

  • you need continuity after a departure
  • you’re hiring, but don’t want to rush the wrong person in
  • the team needs direction and alignment more than “more hands”
  • you’re in a regulated context and can’t afford drift
  • reliability is shaky and incidents are starting to distract the organisation
  • delivery is happening, but it’s not predictable
  • your business is growing, and your current operating model is getting stretched

It also serves well when you need support across multiple areas (technology, operations, security, sometimes HR), but it is not enough to justify separate full-time hires.

What fractional engagement can look like in practice

This isn’t about parachuting in and trying to “run the show”. The goal is to stabilise, set direction, and make the team stronger.

A typical engagement might involve:

  • an initial discovery phase (what’s happening, what’s stuck, what’s risky)
  • a clear 30/60/90-day plan of action to get unstuck and get things flowing.
  • a simple weekly cadence with leadership and team touchpoints
  • decision support for architecture, delivery, hiring, and risk
  • help creating an operating rhythm: ownership, metrics, and follow-through
  • clean handover when the time is right — either to a new hire or an internal leader

That last part matters. Fractional should leave the company in a better place than it found it, not dependent on an external person.

What it’s not

It’s worth being clear about what this is not:

  • It’s not paying for a permanent C-level seat without commitment.
  • It’s not a slide deck and a set of recommendations.
  • It’s not a ticket-taking role or “extra developer capacity”.
  • It’s not taking ownership away from founders or the team.

Fractional leadership works best when it supports decision-making and execution, while ownership stays where it belongs.

A good question to ask yourself:

If you’re in that vacuum right now, or you can see it coming, do you need the experienced guidance, continuity and a clear plan while you stabilise now, and decide what to do next, giving you proper time to find the right long-term solution, without pressure? 

If you find yourself in this very position, let’s talk!
Book a meeting with us – click the link!

Posted on

Public Services Malta – VCARDS

Just for your convenience
.. to easily import into your phone, should you need them.

The source of the information comes from the Malta Department of Information.

Malta Services contact list

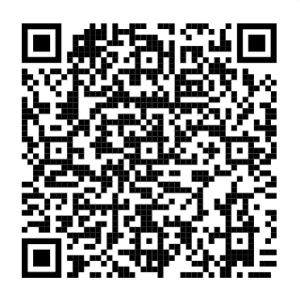
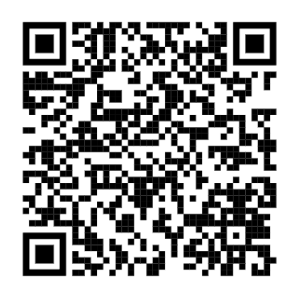
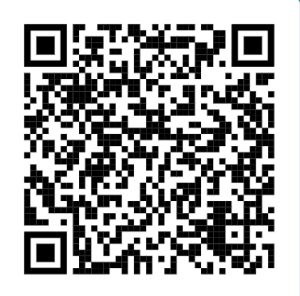
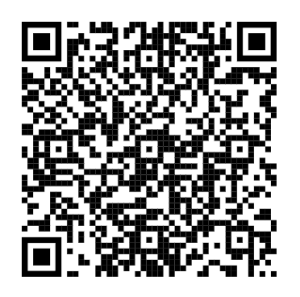
Service Phone number VCARD – Scan to import the contacts to your phone.
Malta Emergency services (all of EU) 112 This can not be imported as it is a
protected number, already on your phone.

Malta Telemedicine Helpline

The free telemedicine helpline service, accessible by dialling 1400, is available to people aged between 16 – 69. It is intended to ease pressure on emergency services by guiding patients to the most appropriate level of care based on their symptoms.

The helpline is meant to be used directly by patients. It targets those who are unsure whether their condition constitutes an emergency.

Patients deemed not to require emergency treatment at Mater Dei will be directed to private hospitals such as Da Vinci, St Thomas or St James’ or to local health centres.

1400 Malta Telemedicine Helpline - 1400

Malta Doctor online
(Not for emergencies!)

Do you feel you need a house visit by a doctor?

A doctor will ask relevant medical questions and decide whether a home visit from the nearest Health Centre is needed.

2122 2444 Malta Doctor online (Not for emergencies!) - 2122 444

Malta Support line

Free 24/7 support line for social, emotional, and crisis situations is 179.
It provides confidential assistance for issues including domestic violence, child abuse, mental health struggles, loneliness, and addiction.

179

Malta Support line - 179

Malta National Mental Health helpline

The 1579 Mental Health Helpline is a 24hr national telephone helpline, providing immediate and free emotional support, advice and practical guidance for anyone in need.
A number of Psychology Professionals, all working within Mental Health Services have undergone training geared towards preparing them to man the Helpline. They work on shifts in order to keep the service going on a 24/7 basis.

1579 Malta National Mental Health helpline - 1579

Malta National support line for victims of crime

The 116006 number is the National Support Line for victims of crime in Malta, operated by the Victim Support Agency (VSA). It provides free, confidential assistance including emotional support, legal guidance, and court case updates from 7:30 am to 7:30 pm, Monday to Sunday, including public holidays. 

116 006 Malta National support line for victims of crime - 116 006

Malta national poisons centre

The Malta National Poisons Centre, reachable by dialing 1774, provides immediate, expert advice for toxic exposures and overdoses. The helpline operates daily from 08:00 to 20:00, including weekends and public holidays. For emergencies outside these hours, visit a local health centre or the Emergency Department at Mater Dei or Gozo General Hospital. 

1774 Malta national poisons centre - 1774

Malta Servizz.gov

Malta general information about government services


153 Malta Servizz.gov - 153
Malta DIER for Employees
(Department for Industrial and Employment relations)
1575 Malta DIER for Employees - 1575
Malta DIER for Employers
(Department for Industrial and Employment relations)
1576 Malta DIER for Employers - 1576

Malta LESA – Collissions

If you are in a road collission. 
Avoid for front to bumper, where the front to bumper form should be used. 

2132 0202 LESA Collissions - 2132 0202


Posted on

Linux wins?

I could not have said this any better myself, as to why there is a silent shift happening.

A few years ago there was a case of Linux having maybe 1 to 1.5% of the desktop,
at best, and right now we’re looking at somewhere between 6 and 7% percent of the
desktop market, depending on where you look, and growing. 

Even in the gaming sector…

This, all of a seemingly sudden after all these years, and it’s rapidly increasing, mainly at the cost of Microsoft, with users moving from Windows to Linux and MAC, and the main reason being mainly due to what is being forced upon the users, the lack of freedoms, the intrusiveness as well as the sudden changes to UI and things that used to work, no longer being there etc.

People want control, ownership, access to THEIR data, privacy, things working consistently without forced sudden changes.

Posted on

Friday Tip – AWS ECS container IP’s?

Have you ever had the problem where you quickly need to know what IP does a container use when running in the ECS?

Well, here’s one for that… 

  • Upload to your cloudshell. 
  • run chmod +x ecs2ip.sh
  • then, execute such as ./ecs2ip.sh dev or ./ecs2ip.sh dev 'container-name'
#!/bin/bash

CLUSTER="$1"
SEARCH="$2"

if [ -z "$CLUSTER" ] 
then
    echo "Usage: $0  ['optional search phrase']"
    exit 1
fi

# Change to match your region, or add as an argument... 
REGION=eu-west-1

TASK_ARNS=$(aws ecs list-tasks \
  --cluster "$CLUSTER" \
  --desired-status RUNNING \
  --region "$REGION" \
  --query 'taskArns' \
  --output text)

[ -z "$TASK_ARNS" ] && echo "No running tasks found" && exit 0

printf '%s\n' $TASK_ARNS | xargs -n100 | while read -r CHUNK; do
  aws ecs describe-tasks \
    --cluster "$CLUSTER" \
    --region "$REGION" \
    --tasks $CHUNK \
    --output json \
  | jq -r '
      .tasks[] as $t
      | (
          $t.attachments[]
          | select(.type=="ElasticNetworkInterface")
          | .details[]
          | select(.name=="privateIPv4Address")
          | .value
        ) as $ip
      | $t.containers[].name as $c
      | "container=\($c) ip=\($ip) taskArn=\($t.taskArn)"
    '
done 2>&1 > /tmp/ecslist.txt 

if [ -z "$SEARCH" ]  
then
   cat /tmp/ecslist.txt 
else
   grep "$SEARCH" /tmp/ecslist.txt 
fi

rm /tmp/ecslist.txt

The output would look something like: 

[cloudshell-user@ip-*****~]$ ./ecs2ip.sh dev container-name
container=container-name ip=10.0.0.1 taskArn=arn:aws:ecs:eu-west-1:**************:task/dev/****…***
container=container-name ip=10.0.0.2 taskArn=arn:aws:ecs:eu-west-1:**************:task/dev/****…***

Njoy!

Posted on

Thoughts on software project sizes – or the pain of scaling.

Thoughts of the Fractional ChiefLines of Code aren’t a quality metric, but they are a cognitive one.

As a codebase grows, the limiting factor isn’t performance or tooling – it’s how much of the system a human can realistically hold in their head.

Past certain size thresholds, individual understanding gives way to structural knowledge, tooling reliance, and eventually team coordination, and this is where documentation, standards, and deliberate technical debt management stop being “nice to have” and become survival requirements.

Ignore this, and critical system knowledge quietly walks out the door one day – possibly for the last time.


While the mythical “LOC” is not an absolute in any way, it is still a usable measure to roughly estimate the complexity and size of a project and by this what you  may need or be able to do with the resources you have. 

The scale of an application, and as echoed by most programmers as a rough measure, is the amount of lines of code one can keep in their head effectively and how much of the “big picture” you start to lose as the code size increases.

This is what I have found to be rough guidelines over time, and while it is my personal perception and a lot of programmers tend to concur, but  may individually have their own varying standards:

  • Tiny – 1,000 lines or less.
    • “Trivial” or a single-problem solution like an individual automation.
    • Easy to keep every tiny detail and every line in your head and know exactly where it is.

  • Small – 1,000-5,000 lines.
    • You know the details of individual modules and functions and within a line range of where to locate a particular set of functionality with ease.
    • You still have deep knowledge of the bulk of the code.
  • Medium – 5,000 to 20,000 lines.
    • You as an individual start losing the detail.
    • You start to focus on the overall structure of the entire project in your head,
      and know roughly what module a particular function exists in and how far in to scroll to find it.
    • You’re only maintaining details of code you’re actively working at this point.
  • Large – 20,000 to 50,000 lines.
    • Detail knowledge is limited to immediate work and everything else is having a birds-eye sense of where stuff is in the code.
    • You’re working off high-level structural knowledge and will start using tools to pinpoint things you’ve forgotten the exact location for.
    • This tends to also be the mental threshold of where an experienced programmer can hold the picture of the entire codebase in their head.

  • Very Large – 50,000 to 250,000+ lines.
    • You’re at multiple team members at this point and you’re treating the codebase as a set of interlocked projects.
    • Coordination for changes is absolutely essential at this point.
    • Only a handful of developers could maintain a complete mental picture of the codebase at this point and would be deep specialists in it having worked on it for years.
    • If this is maintained by a smaller team, or worse, an individual, you need to ensure standards and proper handovers when (not if) people move jobs, where the maintaining experience and knowledge literally walks out of the door every night, and at some point, for the last time. 

Please keep in mind that:

  • These thresholds describe individual cognitive limits, not team or system limits, and that 100k LOC in one tangled domain/monolith is not the same as the same 100k LOC across cleanly separated domains such as that of miniservices (see the article about “when microservices go rogue”).

  • The numbers can be skewed upwards significantly by things like the following (in no specific order)

    • Good coding standards and principles. 
    • Good tools and IDE’s supporting the developers, such as the Jetbrains and similar toolchains.
    • Good specifications. (this is where you start…)
    • Good documentation (Sorry guys – no, code is NOT the documentation – it is the implementation – what you did..)
    • Documentation is what describes in simple terms, how things hang together, used data formats, connectivity, data and service relations, related services etc , and, the intent of what you did – not what you did.
    • Good processes supporting the development coupled with development time frames allowing for the above.
    • Continuously caring about technical debt, setting aside time “decruft” the bad stuff.

(C) (BY) EmberLabs / Chris Sprucefield

Posted on

Making a JKS keystore from PEM

Just thought I would share this snippet with you all..
This does the conversion of the pem file to Java Key Store format.

#!/bin/bash
# Alter path to your java keytool.
keytool="/etc/alternatives/keytool"
PASS="<insert keystore pass here>"
ALIAS="<app name>"
keyfile="./yourdomain.key"
rootfile="./yourdomain.ca-bundle"
certfile="./yourdomain.crt"
bundlefile="bundle.cer"
destkeystore="keystore.jks"
cat ${certfile} ${rootfile} > ${bundlefile}

openssl pkcs12 -export -in ${bundlefile} -inkey ${keyfile} -out server.p12 -name ${ALIAS} -CAfile ${bundlefile} -caname root
# Export the pkcs12 to a jks file.
${keytool} -importkeystore -deststorepass ${PASS} -destkeypass ${PASS} -destkeystore ${destkeystore} -srckeystore server.p12 -srcstoretype PKCS12 -srcstorepass ${PASS} -alias ${ALIAS}
# Convert the jks to a pkcs12 type keystore
${keytool} -importkeystore -srcstorepass ${PASS} -srckeystore ${destkeystore} -destkeystore ${destkeystore} -deststoretype pkcs12